We use Claude, GPT, Gemini and open models side by side, routing each request to the model that fits its difficulty, sensitivity and cost.
Simple classification goes to a small, cheap model; complex reasoning goes to a frontier model.
Anything containing personal or confidential data stays on a private model.
Swap or add providers behind one interface, with no change to your application.
Budgets and caps per team, per feature and per month.
Private and local first for critical and sensitive data. Partnered cloud models only when a task needs them, behind a policy gate, with audit logs and monitoring you can see.
What we use for LLMs & multi-model, and what each piece is for.
A working AI product in your users' hands in seven days, built on our proven components.
No-obligation free MVP for startups. Scope agreed in the free consultation; you keep it either way.
Built your app with AI coding tools but it isn't secure or won't scale? We review it free and fix the critical security and scaling issues free.
Long documents, careful reasoning, drafting; via the Claude Partner Network
General reasoning, tools and structured output; OpenAI Select Partner
Multimodal and long-context work
Strong general open model for private deployment
Efficient open models for high-volume tasks
Multilingual and specialised open models
Enterprise hosting with regional data residency
Managed access to several model families in your AWS account
Serving open models on your own hardware
One endpoint: auth, policy, redaction, routing, logs
Golden task sets scored for accuracy, cost, latency
Caps per team, feature and month
Typical phases and timelines; your plan is agreed after the free consultation.
Where models are used today and what it costs
1 weekTasks mapped to models, with evaluation sets
1–2 weeksPolicy, redaction, routing and dashboards
2–4 weeksMonthly review of cost, quality and new models
OngoingFrom products we built and run, and engagements we measured.
Each matter chooses its model: on-device via Ollama for privileged work, Claude, OpenAI or Gemini where allowed, or an air-gapped Private AI Box.
An OpenAI-compatible gateway tracking 31 models across 242 tenants, with budgets and routing per team.
The technical detail, for your engineers.
Applications call one OpenAI-compatible endpoint; the gateway authenticates, applies policy, redacts, routes and logs.
Task type, input length, detected sensitivity, required latency, and per-team budget.
Each route is tested on a golden set of your real tasks for accuracy, cost and latency before it goes live.
Claude (Claude Partner Network), OpenAI (Select Partner), Gemini, Azure OpenAI, AWS Bedrock, and open models such as Llama and Mistral run privately.
No. Your app talks to one gateway endpoint; models change behind it.
No. Enterprise agreements and private models only; nothing trains anyone else's model.
It depends on your task mix; we measure it on your real traffic before you commit.
The one that passes your evaluation set at the lowest cost and risk; it's usually more than one.
Yes. The gateway works with your own accounts and keys.
Routing takes latency into account; fast models handle interactive tasks, larger ones handle background work.
On a golden set of your real tasks, scored for accuracy, cost and latency, repeated whenever a new model arrives.
Yes. Spend and usage are broken down by team, feature and model.
No. We use private models or enterprise agreements that forbid training on your data.
Book the free two-hour consultation. We look at one real workflow and tell you whether this technology fits.
Yes. Engagements we take on carry our 10× productivity guarantee on the agreed workflow, or the fee comes back.
 Thumbnail:
assets/img/projects/lexedge.png
One AI workspace for legal drafting, research and citation checks
240+ practices using it Thumbnail:
assets/img/projects/neuralgate.png
Observability, governance and security for every LLM request
4.8M+ requests intercepted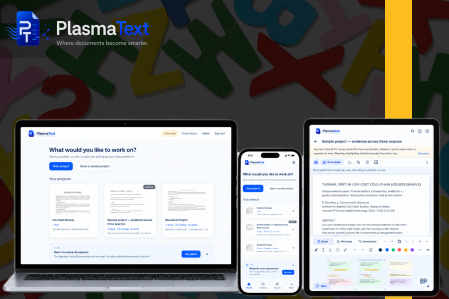 Thumbnail:
assets/img/projects/plasmatext.png
Research workspace where every AI answer cites its page
23 report templatesTwo free hours on a real workflow. We'll tell you whether it fits, and what it would take.
Download